
Japanese text on signs and how many people MOSS-Image can place: two quick tests on a 12 GB card
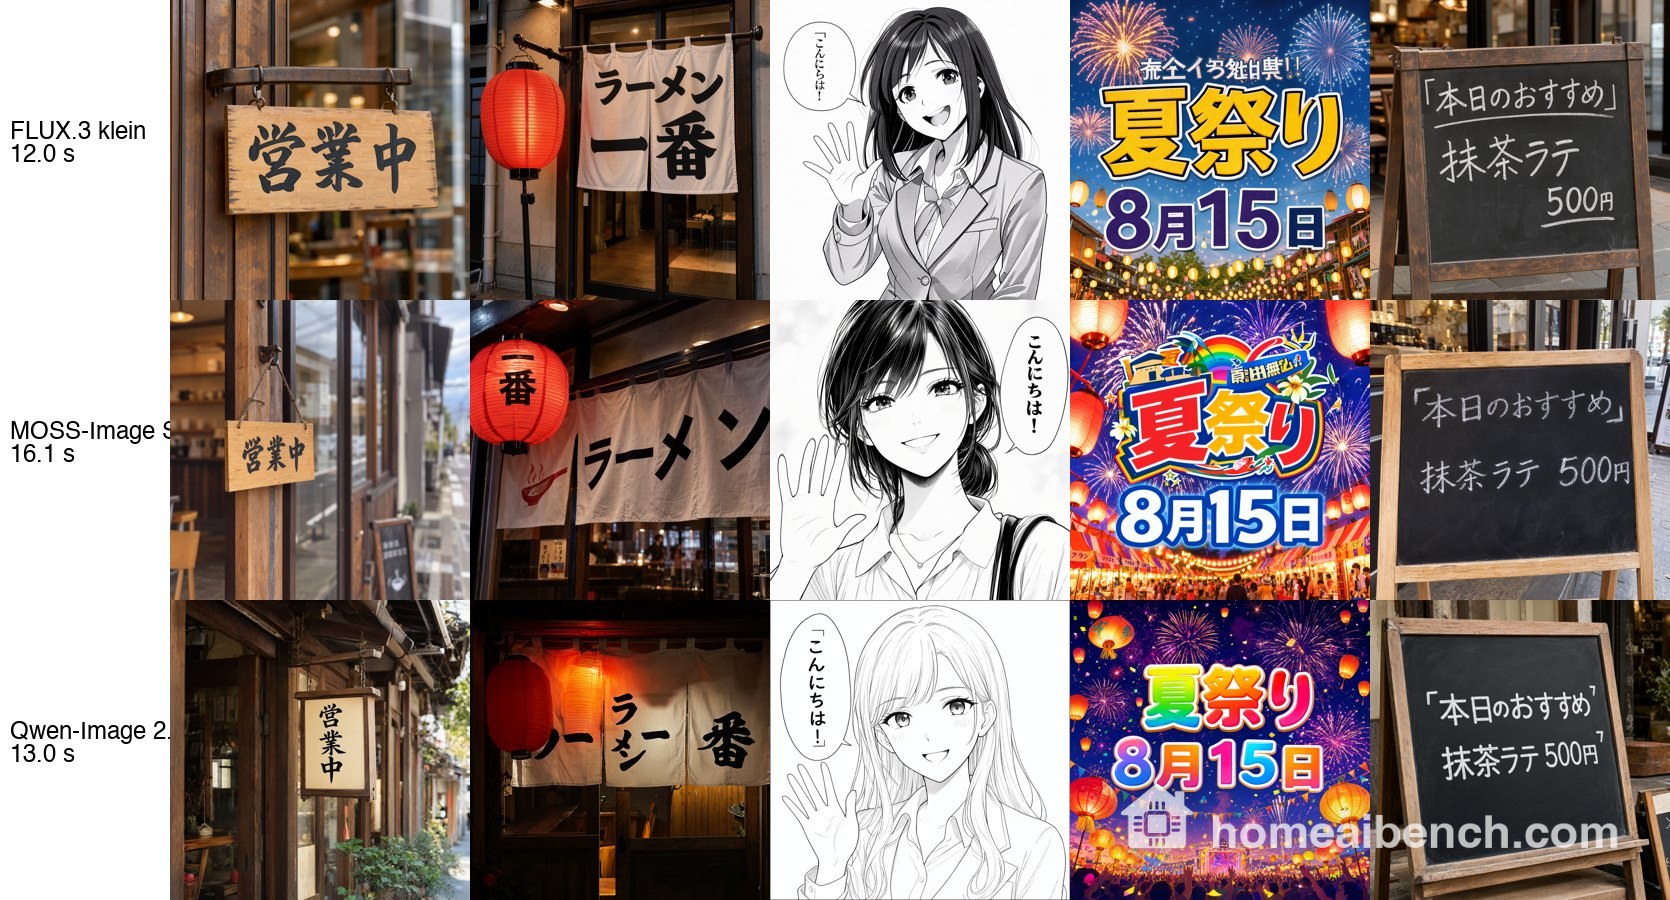
English words such as "OPEN" were spelled correctly by every recent model in our standard set, so we tried two harder things: Japanese text, and placing a given number of people with MOSS-Image's layout boxes. Both ideas came from people testing these models on X, in particular @sep_is_heim, who runs the same kind of 12 GB card at home.
Test 1: Japanese text
Five prompts, each with the exact text in quotes: a cafe sign 「営業中」, a ramen-shop curtain 「ラーメン 一番」, a manga speech bubble 「こんにちは!」, a festival poster 「夏祭り」「8月15日」, and a chalk menu 「本日のおすすめ」「抹茶ラテ」「500円」. Two seeds (300, 301), 1024×1024, each model at its usual settings, one rented RTX 5070 per model. We counted a string as correct only if every character was right; extra stray characters elsewhere were noted but not counted as a miss.
| Model | Strings correct (of 18) | Median per picture |
|---|---|---|
| MOSS-Image SFT (25 steps) | 18 | 16.1 s |
| FLUX.3 klein (15 steps) | 17 | 12.0 s |
| Qwen-Image 2.1 (25 steps) | 16 | 13.0 s |
| Krea 2 Turbo | no pictures | – |
- MOSS-Image wrote every string correctly in both seeds. One poster added a short line of made-up characters above the title.
- FLUX.3 klein missed one character once: 「こんにらは!」 instead of 「こんにちは!」. One curtain repeated 「番」 and one poster added a line of made-up characters.
- Qwen-Image 2.1 split 「ラーメン 一番」 across the panels of the curtain in one seed so that it no longer read correctly, and wrapped the menu text in extra brackets.
- Krea 2 Turbo produced nothing: on two separate runs every request timed out after 110 seconds or returned HTTP 503. Its standard set ran normally two days ago at 12.8 s per picture; we have not found the cause.
Two seeds per prompt is small. Treat the table as "all three can write short Japanese text on a 12 GB card", not as a ranking.
Test 2: how many people can MOSS-Image place?
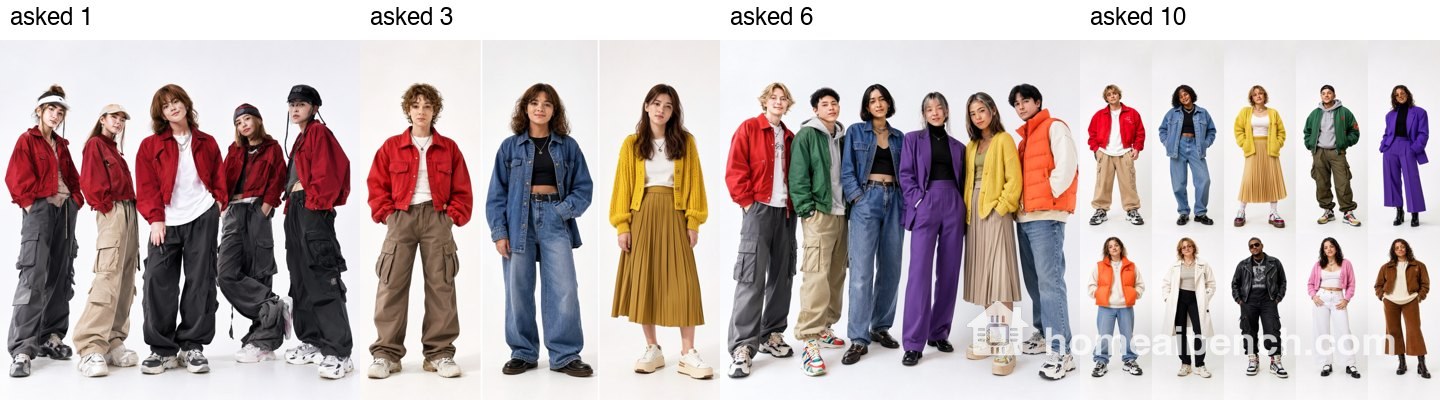
MOSS-Image accepts a JSON layout as the prompt, with a box (bbox) for each item (official guide). We asked for 1, 3, 6 and 10 adults, each person in their own box and in a different outfit, ten seeds each, and counted a picture as correct when the number of people and the outfits matched.
| People asked for | Correct count and outfits (of 10) |
|---|---|
| 1 | 2 |
| 3 | 10 |
| 6 | 9 (all six in one row instead of two) |
| 10 | 9 |
- Three, six and ten people worked almost every time, and the outfit of each box went to the right person.
- One person was the failure: eight of ten pictures showed four to six people, all dressed alike. A first run with plainer prompts did the same (0 of 10). We have not found why; the layout for one person is simply a single large box.
- With six people the model ignored the two-row layout and stood everyone in one row, in a different order.
- Many pictures look like several separate studio shots placed side by side, even though we asked for a single photograph.
- Our first run dressed everyone in plain t-shirts; for the second run we wrote specific current outfits for each person (boxy jackets, barrel-leg trousers, pleated midi skirts), which is what you see here.
How much to trust this
- One machine per model, two seeds for the text test and ten for the layout test.
- We wrote the layouts ourselves and did not use MOSS's layout helper.
- We do not score image quality.