
Training a Z-Image LoRA on a Mac: eleven failures, one patched line, no face
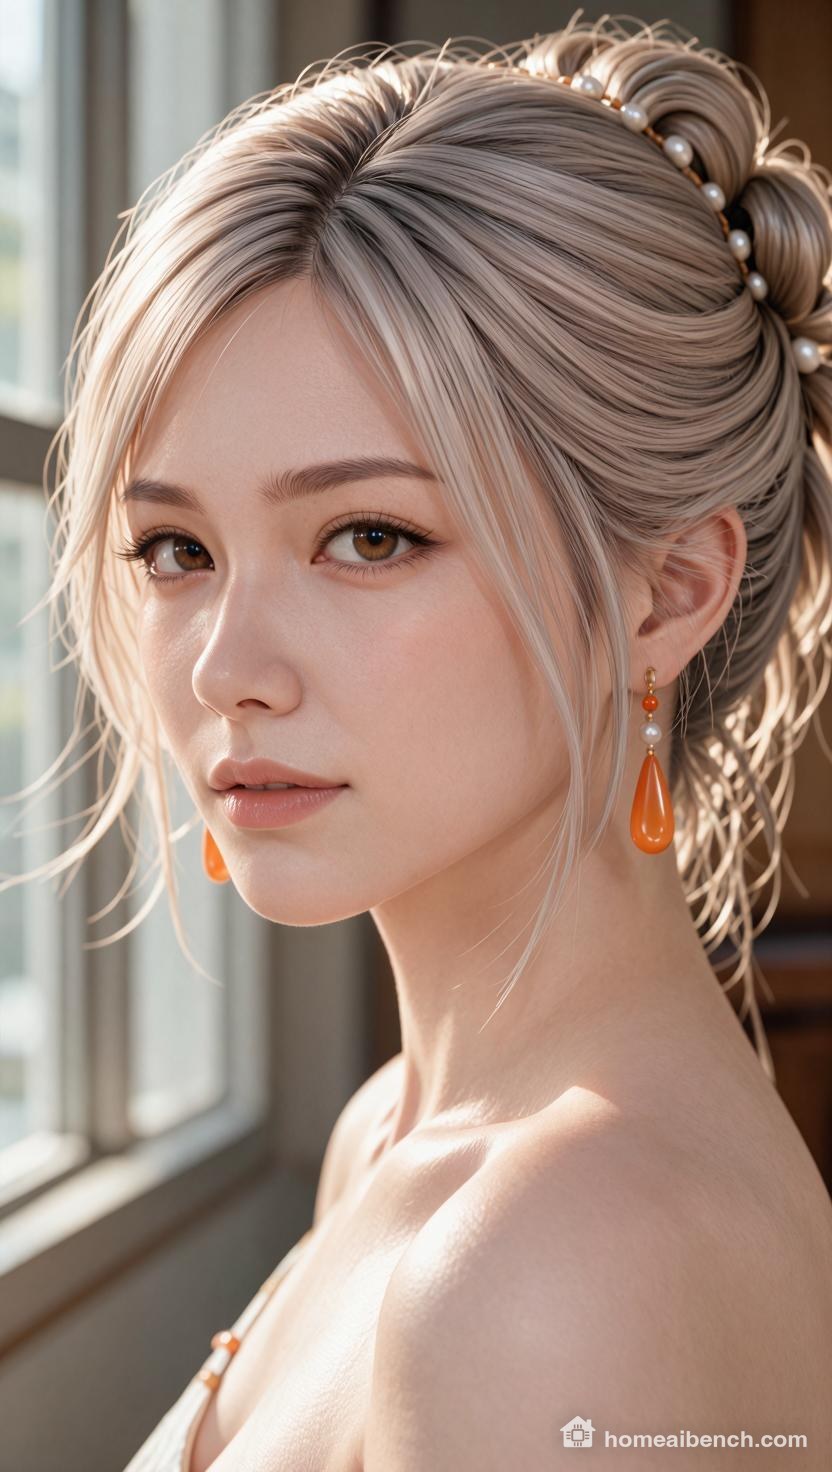
*Our Qwen-Image LoRA had shown that one fixed character could be held by a small dataset and a modest training run. We next tried Z-Image-Turbo, a distilled text-to-image model from Tongyi-MAI, to see whether it could do the same job with a different base model.*
The goal was narrow. We were not testing whether Z-Image-Turbo could make good images in general. We wanted a LoRA that preserved one fixed character. Because the base model is distilled, training it also uses the de-distillation adapter ai-toolkit provides for it, about 340 MB, loaded alongside the base model. The trainer was ai-toolkit, and the dataset was the same 52 images used in our earlier Qwen-Image work.
Eleven ways to fail on a rented GPU
The first route was rented cloud GPUs in the 24 GB class. Eleven consecutive runs failed. The total spend was only about $2.40, but the pattern was more instructive than the amount.
The causes were mostly ordinary: configuration mistakes of ours, a torch version mismatch, system RAM exhaustion, a full disk, and VRAM limits. Other runs stalled at about 12 minutes per step with layer offloading. What the $2.40 bought was eleven variations on a dead end, with no way to debug any of them from outside. So we stopped renting and moved the job to a machine of our own, where we could watch it fail up close.
The bug was in the cache
We moved the job to an in-house Apple M1 Max Mac with 64 GB of memory and the MPS backend. The change of machine made the underlying problem visible.
Before training, ai-toolkit pre-computes text embeddings and stores them in a cache. The dataloader encoded those embeddings in batches of 16, set by the constant TEXT_EMBED_CACHE_BATCH = 16. During batched encoding, memory grew without bound. A single encode took about 20 seconds on CPU with stable memory; a batch of 16 grew by gigabytes per minute.
The fix was one line: patch the batch size from 16 to 1. Caching our dataset then completed in about 32 minutes, for just over a hundred items. That same caching step is what the rented jobs had been running too. At least in large part, the rented-GPU failures were a preprocessing bug with expensive timing.
MPS ground rules
Running ai-toolkit on Apple silicon required a few firm rules:
- Use plain AdamW. The 8-bit AdamW implementation from bitsandbytes is CUDA-only.
- Keep gradient checkpointing on. Turning it off exhausted memory immediately, with 86.7 of 88.1 GiB allocated.
- Do not assume quantization will rescue the run. One quantized attempt froze outright during caching, stuck at the first of 52 items for about 50 minutes while swap grew by 35 GB, until we stopped the job by hand.
The working configuration was MPS, bf16, no quantization, gradient checkpointing on, plain AdamW, and the one-line cache patch. Training then ran at about 34–37 seconds per step. Sample generation was much slower, at about 9 minutes per image, but it was steady enough for an unattended run.
1,500 steps, and the face is wrong
The first full run reached 1,500 steps in just under 14 hours of training — about 16 hours wall-clock, counting the sample generation between checkpoints. Checkpoints were saved every 250 steps, at about 170 MB each. The final training loss was 0.368.
By the loss curve alone, the run looked respectable. By the samples, it had missed the point. The face read as an older woman, not as our character. A LoRA can optimise the objective and still fail the only test that matters here: whether the same person appears when the model is asked for her. We did not adopt the result.
Extending the run
Extending training turned out to be simpler than expected. Keeping the same training folder and job name, and raising the steps value in the configuration, was enough. The toolkit found the step-1500 checkpoint in its metadata and resumed from there, optimizer state included.
| Total steps | Final loss | Verdict |
|---|---|---|
| 1,500 | 0.368 | The face reads as an older woman; not our character |
| 2,000 | 0.373 | Likeness visibly improves; the high point of the run |
| 3,000 | 0.448 | Some improvement, but the face never lands |
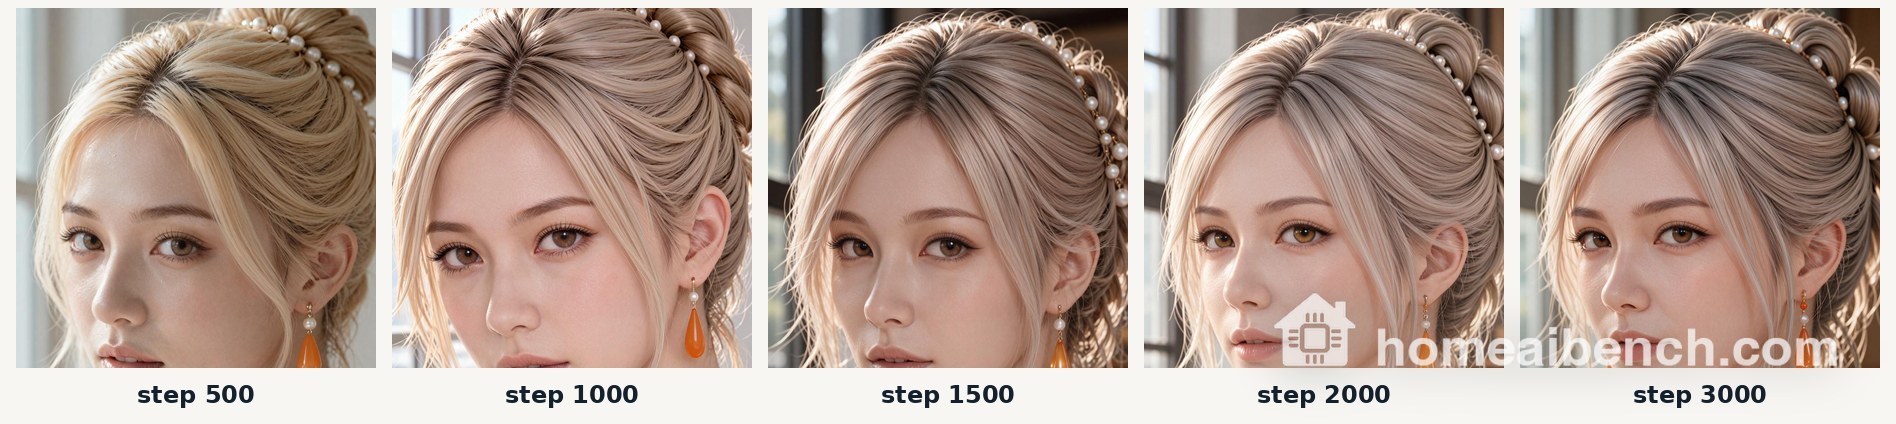
The first extension, from 1,500 to 2,000 steps, was the useful one. Loss was essentially flat, 0.373 against 0.368, but the face moved visibly closer to the character — the warmest verdict any Z-Image sample had earned. That encouraged a second extension to 3,000 steps. It took the final loss to 0.448. Some aspects of the face improved, but identity still did not land. Two traits did not move at all through any extension: silver-grey hair and a braided bun.
The dataset's centre of gravity
Those two traits were explained by our later audit of the training data. In the 52-image set this run trained on, about 90 percent of the images deviate from the specified hair colour — silver-grey instead of the warm tone — and about 56 percent wear braided styles. The audit's conclusion: Z-Image had not invented those features, or failed to learn them. It had converged to the dataset's centre of gravity, and doubling the training from 1,500 to 3,000 steps did not pull it out.
That is the uncomfortable consistency we keep meeting in this work. The Qwen-Image run showed that a small dataset can carry a character. The audit showed how far that dataset was from its own written specification. The Z-Image run showed the same problem from the other side: when the central tendencies of the data conflict with the intended character, more steps did not correct the centre — in this run they mostly sharpened it.
What we kept
We closed the Z-Image line for this character. That verdict is narrower than it sounds. The base model itself remains usable for work where a fixed identity does not matter; we use it for exactly that. It was this pairing — distilled base, this dataset, this character — that did not produce an adoptable LoRA.
Three things were worth keeping:
- The one-line cache patch. Changing the text-embedding cache batch size from 16 to 1 removed the unbounded memory growth that had made the preprocessing stage so destructive.
- The MPS recipe. With bf16, no quantization, gradient checkpointing on, plain AdamW, and the cache patch, ai-toolkit became usable on our Apple silicon machine.
- A warning about loss. The final losses at step 1,500 and step 2,000 differ by only 0.005 — yet the samples were judged visibly different in likeness. The loss told us that training was proceeding. It told us almost nothing about likeness.
The rented failures cost about $2.40 in total. The successful runs used our own hardware, so their cost was time rather than rental fees: just under 14 hours of training for the first 1,500 steps, about four and a half hours for the +500 extension, and about ten hours end to end for the +1,000.
Methods
*Training used ai-toolkit with Z-Image-Turbo and the de-distillation adapter provided for it. The dataset was the same set of 52 images used for the earlier Qwen-Image LoRA, scored later in the dataset audit. The completed configuration was Apple M1 Max with 64 GB of memory, MPS backend, bf16, no quantization, gradient checkpointing enabled, plain AdamW, and text-embedding cache batch size patched from 16 to 1. Checkpoints were saved every 250 steps. Training samples used two fixed prompts; the face comparison in this note uses the close-up one. Losses are the final values reported by the trainer; likeness was judged visually, not from the loss curve.*