
Four open video models on a 16GB GPU: Wan 2.2, LTX-2.3, LTX-2.5 and HunyuanVideo 1.5
*Cloud video APIs keep getting better, but the open-weight scene moved fast this year. We shortlisted the four open image-to-video models that dominate the current discussion — Wan 2.2, LTX-2.3, LTX-2.5 and HunyuanVideo 1.5 — put them on a single consumer GPU, and ran the same clip through all of them. The interesting results were not the headline speeds. They were the three things nobody's spec sheet tells you: whether the model actually keeps your start image, whether the LTX family's generated audio is real, and where the memory wall actually is.*
Setup
- GPU: NVIDIA GeForce RTX 5070 Ti, 16GB VRAM (in a PCIe 3.0 x4 slot on this host, so expect slower model loads than an x16 desktop; sampling itself is compute-bound)
- Host: Ryzen 9 3900X, 64GB RAM; the ComfyUI service is capped at 48GB RAM
- Software: ComfyUI 0.45.0, PyTorch 2.14.1+cu130, driver 595.91.07
- Every run: service restarted first, so timings include model loading. RAM is the service's systemd MemoryPeak; VRAM is the nvidia-smi peak.
Method
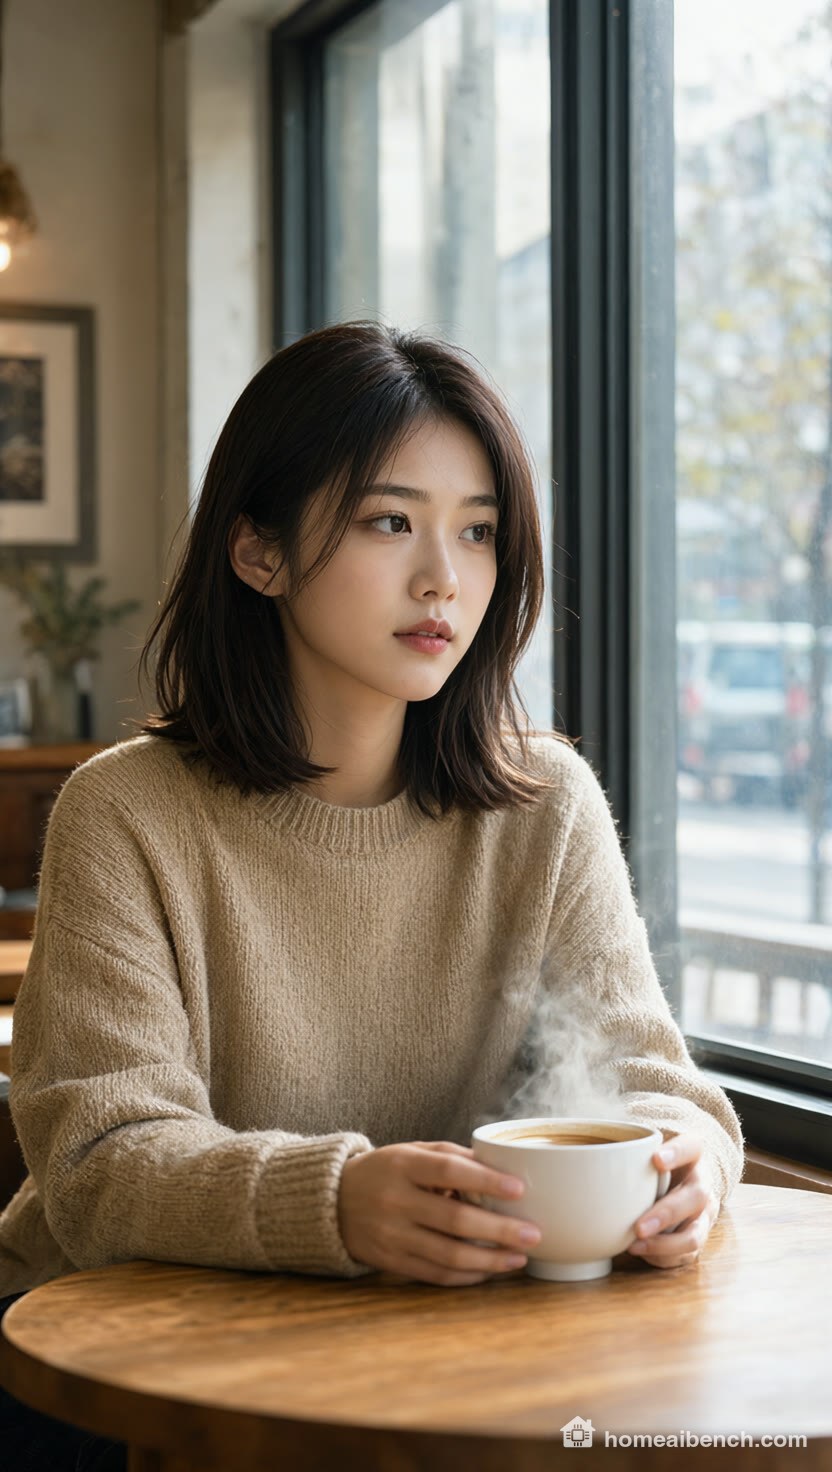
One start image for everything: a woman in a beige sweater holding a coffee cup in a cafe, generated locally with Qwen-Image-2.1 (no LoRA). One motion prompt for everything:
> The woman lifts the coffee cup with both hands and takes a small sip, then lowers it and smiles softly while looking out the window, steam rising from the cup, her hair swaying gently, photorealistic, static camera
Base spec: 480×832, 49 frames, 24 fps (a 2-second clip), seed 99. Each model ran at its standard ComfyUI configuration — step counts differ by design (Wan 20 steps, LTX distilled 8 steps, Hunyuan 20 steps), because the question was "what do you get out of the box", not "what wins at equal steps".
Round 1: the base comparison
| Model (build) | Time | VRAM | RAM | Start image kept? | Prompt arc |
|---|---|---|---|---|---|
| Wan 2.2 TI2V-5B fp16 | 60.0 s | 15.2 GB | 21.4 GB | Yes | Lift and sip completed |
| LTX-2.5 22B distilled, int8 convrot | 75.2 s | 15.8 GB | 42.8 GB | Yes | Lift, sip, smile |
| LTX-2.3 22B dev fp8 + distilled LoRA 0.5 | 98.1 s | 15.8 GB | 46.4 GB | Yes | Full arc incl. smile to window |
| HunyuanVideo 1.5 480p i2v fp16 | 204.2 s | 15.8 GB | 31.6 GB | No (see below) | Became a different video |
Three of the four pin the start image into the latent (Wan and LTX encode it directly), and it shows: same woman, same cafe, same cup, start to finish. HunyuanVideo 1.5, in our first run, simply wandered off — a different woman, a paper takeout cup, a plain wall. It produced a perfectly decent text-to-video clip; it did not produce *our* clip.
That result turned out to be our wiring error, not the model — the story is in round 2b below, and with the workflow fixed, Hunyuan holds the start image as well as anyone (206.1 s, same memory class). It remains the slowest of the four by a wide margin, but it is a real image-to-video model. We left the mistake in this note because diagnosing it taught us more than the benchmark did.
Wan 2.2's 5B is the sprinter: fastest, and less than half the RAM of either LTX. The LTX pair trades RAM for features, which brings us to round 2.
Round 2a: is LTX's synchronized audio real?
LTX-2.3 and 2.5 are the only models *in this test* that generate audio and video in one pass (they are not the only open-weight models with the feature — Character.AI's Ovi does it too, and is on our list for a follow-up). Every demo claims it; we wanted a receipt. Same cafe setup on LTX-2.5, prompt extended with a spoken line — *"It smells wonderful"* — plus cafe ambience. 88.5 s later the mp4 contained a real AAC stereo track (48 kHz, mean −19.2 dB — not silence, not noise). We ran the generated audio through Whisper (base). Transcription, verbatim:
> It smells wonderful.
Prompted speech, intelligible, generated locally on 16GB in the same pass as the video. That is a genuinely different capability class from everything else in this test.
Round 2b: the knob that does nothing — and the wire that wasn't connected
Hunyuan's text-encode node has an image_interleave parameter for how the reference image's embeddings interleave with the text tokens, so the obvious first fix for round 1 was to lower it from 2 to 1 and rerun. 208.1 s later, the sampled frames were byte-identical to the first run — same SHA-256 on frames 24 and 48. In this path, the knob changes nothing.
The actual bug was ours. ComfyUI's HunyuanVideo 1.5 image-to-video node takes the start image through *two* routes: vision features into the text encoder (which is what we had wired), and an optional start_image input that VAE-encodes the frame into the latent — the same anchoring mechanism Wan and LTX use. We had never connected it. One rerun with the wire in place (206.1 s): same woman, same cafe, same cup, start to finish.
Two lessons, both worth more than the benchmark. When a knob produces a bit-identical output, believe the hash, not the documentation. And when a model "can't do" something its peers can, check your own graph before you publish the conclusion — our fact-checker caught this one by reading the node source, which is exactly why the fact-check step exists.
Round 2c: 720p, and the wall that wasn't there
LTX-2.3 already peaked at 46.4GB RAM at 480p, against our 48GB cap, so the expectation was that 736×1280 (LTX needs multiples of 32) would break it. It didn't:
| Model | 736×1280 time | VRAM | RAM |
|---|---|---|---|
| Wan 2.2 5B | 114.1 s | 15.7 GB | 22.3 GB |
| LTX-2.5 | 88.7 s | 15.8 GB | 44.9 GB |
| LTX-2.3 | 98.3 s | 15.7 GB | 45.9 GB |
LTX's RAM footprint is dominated by resident weights (a ~29GB checkpoint plus a ~9.4GB text encoder), not by activations at these sizes. Resolution, within this range, is nearly free.
So we hunted at duration instead: 121 frames (5 seconds) at 480×832. Same story. Wan 5B: 110.1 s, RAM 22.2GB. LTX-2.5: 88.3 s, RAM 45.2GB. LTX-2.3: 100.1 s, RAM 46.0GB — in every case within a few percent of the same model's 49-frame numbers, and the final frames show no visible identity drift. Inside the envelope of 2–5 second clips at up to 736×1280, there is no memory wall on this hardware; the wall, if you go looking for it, lives at 1080p-class output, 10+ second durations, or in the two-stage upscale workflow. We report the negative result because "we expected it to break and it didn't" is the most useful sentence in this whole note for anyone speccing a similar machine.
Round 2d: the 27B flagship on a 16GB card
Wan 2.2's A14B is a 27B mixture-of-experts (two ~14B experts, high-noise and low-noise). In GGUF Q5_K_M form (QuantStack build, 10.79GB per expert) plus the fp8 text encoder, it fits: 436.2 s, VRAM peak 14.3GB, RAM peak 36.5GB. The output was the most natural of the set — the least "animated" motion, the start image held perfectly. It is also 7.3× slower than the 5B — in its stock configuration. Adding the LightX2V 4-step distillation LoRAs (one per expert, CFG 1.0, steps split 2/2 at the noise boundary) changed the picture completely: 76.2 s, VRAM 14.4GB, RAM peak just 17.2GB, and in our sampled frames the motion arc was, if anything, *more* complete than the 20-step run — she actually reaches the sip. The flagship at 5B-like speed is the single most practical finding in this test: budget the download (21.6GB of GGUF experts plus 2.5GB of LoRAs; the 6.7GB fp8 text encoder is shared with the 5B install), not the runtime.
Cost note
The marginal cost of a local clip is electricity. At roughly 450W wall draw for GPU plus host, a 100-second generation is about 0.0125 kWh — well under ¥1 at typical Japanese residential rates. Hosted Wan-class APIs charge on the order of $0.65 for a 10-second clip (fal.ai lists Wan 2.2 A14B image-to-video at $0.04–0.08 per billed second depending on resolution). The local card does not win on speed or convenience; it wins on marginal cost and on keeping the inputs on your own disk.
Takeaways
- Fast and light: Wan 2.2 5B. Half the RAM of everything else, quickest turnaround, faithful to the start image.
- Features: LTX-2.5. The only route to one-pass synchronized audio, nearly as fast as Wan at 720p-class resolutions in its int8 distilled build, at the price of ~43GB RAM.
- Maximum fidelity: Wan 2.2 A14B via GGUF with the LightX2V LoRAs — flagship quality at 76 seconds a clip; the undistilled 20-step route (436 s) buys nothing visible in this test.
- Slowest, and check your wiring: HunyuanVideo 1.5 anchors the start frame properly once its latent
start_imageinput is connected — but it took us one wrong run, one inert knob, and a fact-check reading the node source to get there, and it is still 3× slower than Wan 5B. "Image-to-video" nodes may offer more than one image path; only one of them is the anchor.
Caveats
One seed per configuration; each model at its own standard settings rather than equalized steps; timings include model load after a cold service restart; a single prompt and a single subject. Quality judgments are from sampled frames (0/24/48) plus full-clip viewing of the finals. HunyuanVideo 1.5 ships under the Tencent Hunyuan Community License, which excludes the EU/UK/South Korea, and requires a separate license from Tencent if your products or services exceeded 100 million monthly active users in the month preceding the model's release; Wan 2.2 is Apache 2.0, LTX-2.3/2.5 carry Lightricks' LTX-2 Community License terms. Check before you build on any of them.